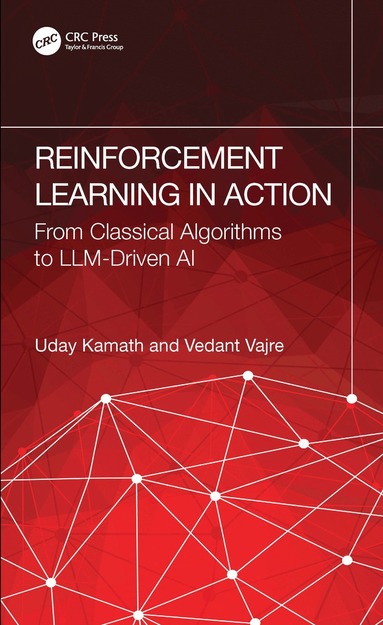
Reinforcement Learning in Action
- Vikt 0,6 kg
765 krhos Bokus · exkl. frakt
234 kr skillnad mellan billigaste och dyraste butik i lager
Dubbelkollat idag
Jämför 2 butiker
- Bokus, 765 kr, frakt enligt butiken. Till butik (öppnas i ny flik)
I lagerFrakt: se butikenDubbelkollad 17:51
765 kr
Lägst
- Akademibokhandeln, 999 kr, frakt enligt butiken. Till butik (öppnas i ny flik)
I lagerFrakt: se butikenDubbelkollad 17:53
999 kr
Priser från butikernas flöden kan ha ändrats: det är priset hos butiken som gäller, så kontrollera det innan du handlar.
Prishistorik
Köp nu eller vänta?
Pris idag
765 kr
- Lägst
- 756 kr
- Snitt
- 761 kr
- Högst
- 768 kr
| 2026-10-03 | 756 kr · Lägst hos Bokus |
|---|---|
| 2026-10-08 | 768 kr · Lägst hos Bokus |
| 2026-10-10 | 767 kr · Lägst hos Bokus |
| 2026-10-11 | 764 kr · Lägst hos Bokus |
| 2026-10-12 | 762 kr · Lägst hos Bokus |
| 2026-10-16 | 765 kr · Lägst hos Bokus |
Om produkten
Reinforcement Learning in Action
Läs merLäs mindre
Reinforcement learning (RL) has become the engine behind some of the most significant advances in modern artificial intelligence, from defeating world champions in Go to aligning large language models with human preferences. Yet despite its central role, RL remains poorly understood by many practitioners who work with these systems daily. Reinforcement Learning in Action: From Foundations to Frontiers bridges the gap between classical RL theory and the cutting-edge techniques driving today's AI breakthroughs. The book traces a complete path from Markov Decision Processes and Bellman equations through deep RL methods (DQN, REINFORCE, Actor-Critic, PPO) to the modern landscape of LLM alignment (RLHF, DPO, SimPO, KTO), reasoning optimization (GRPO, VinePPO, MCTS), and agentic systems with tool use, memory, and multi-turn planning. A distinguishing feature is the book's consistent five-layer pedagogical structure: each algorithm is presented with its key characteristics, a full mathematical derivation, an honest assessment of its advantages and limitations, a complete from-scratch Python/PyTorch implementation in which variable names match the equations, and a hands-on case study with reproducible experiments. Case studies progress from Grid World navigation and CartPole control to fine-tuning language models with DPO on the HuggingFace ecosystem, training reasoning models with GRPO on mathematical benchmarks, and building a full agentic customer support system. Written for ML engineers, researchers, and advanced students, this book provides both the conceptual depth and implementation fluency needed to understand, build, and extend the RL systems shaping the future of AI.
Specifikationer
Fakta
- Vikt
- 0,6 kg
- GTIN
- 09781041130819
Uppgifter från tillverkare och butiker.