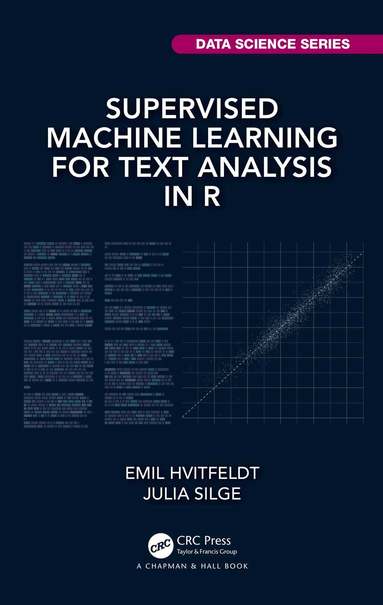
Supervised Machine Learning for Text Analysis in R
- Vikt 0,56 kg
852 krhos Bokus · exkl. frakt
257 kr skillnad mellan billigaste och dyraste butik i lager
Dubbelkollat idag
Jämför 2 butiker
- Bokus, 852 kr, frakt enligt butiken. Till butik (öppnas i ny flik)
I lagerFrakt: se butikenDubbelkollad 19:51
852 kr
Lägst
- Akademibokhandeln, 1 109 kr, frakt enligt butiken. Till butik (öppnas i ny flik)
I lagerFrakt: se butikenDubbelkollad 19:53
1 109 kr
Priser från butikernas flöden kan ha ändrats: det är priset hos butiken som gäller, så kontrollera det innan du handlar.
Prishistorik
Köp nu eller vänta?
Just nu kostar produkten 852 kr — 16 kr över det lägsta vi sett på 3 veckor.
Under den tiden har det oftast legat runt 840–850 kr.
Pris idag
852 kr
- Lägst
- 836 kr
- Snitt
- 856 kr
- Högst
- 1 089 kr
| 2026-09-24 | 1 089 kr · Lägst hos Akademibokhandeln |
|---|---|
| 2026-09-25 | 836 kr · Lägst hos Bokus |
| 2026-09-30 | 837 kr · Lägst hos Bokus |
| 2026-10-03 | 843 kr · Lägst hos Bokus |
| 2026-10-04 | 846 kr · Lägst hos Bokus |
| 2026-10-07 | 855 kr · Lägst hos Bokus |
| 2026-10-10 | 854 kr · Lägst hos Bokus |
| 2026-10-11 | 851 kr · Lägst hos Bokus |
| 2026-10-12 | 849 kr · Lägst hos Bokus |
| 2026-10-16 | 852 kr · Lägst hos Bokus |
Om produkten
Supervised Machine Learning for Text Analysis in R
Läs merLäs mindre
Text data is important for many domains, from healthcare to marketing to the digital humanities, but specialized approaches are necessary to create features for machine learning from language. Supervised Machine Learning for Text Analysis in R explains how to preprocess text data for modeling, train models, and evaluate model performance using tools from the tidyverse and tidymodels ecosystem. Models like these can be used to make predictions for new observations, to understand what natural language features or characteristics contribute to differences in the output, and more. If you are already familiar with the basics of predictive modeling, use the comprehensive, detailed examples in this book to extend your skills to the domain of natural language processing. This book provides practical guidance and directly applicable knowledge for data scientists and analysts who want to integrate unstructured text data into their modeling pipelines. Learn how to use text data for both regression and classification tasks, and how to apply more straightforward algorithms like regularized regression or support vector machines as well as deep learning approaches. Natural language must be dramatically transformed to be ready for computation, so we explore typical text preprocessing and feature engineering steps like tokenization and word embeddings from the ground up. These steps influence model results in ways we can measure, both in terms of model metrics and other tangible consequences such as how fair or appropriate model results are.
Specifikationer
Fakta
- Vikt
- 0,56 kg
- GTIN
- 09780367554194
Uppgifter från tillverkare och butiker.